Teranode Microservices Overview¶
Index¶
- Teranode Microservices Overview
1. Introduction¶
Teranode is designed as a collection of microservices that work together to provide a horizontally scalable and highly efficient blockchain network. The microservices architecture enables Teranode to achieve exceptional throughput exceeding 1 million transactions per second by distributing processing across multiple machines and allowing most services to scale independently based on demand.
This architectural approach provides several key advantages:
- Horizontal Scalability: Services can be deployed across multiple machines, enabling the system to handle increasing transaction volumes by adding more compute resources
- Independent Scaling: Most services can be scaled independently based on their specific resource requirements and bottlenecks (see the caveat below)
- Distributed Processing: Work is distributed across specialized services that communicate asynchronously through Kafka and synchronously via gRPC
- Fault Isolation: Issues in one service are contained and don't cascade to affect the entire system
- Technology Flexibility: Each service can use the most appropriate technology stack and storage backend for its specific requirements
Scaling caveat: the first two points above do not apply to every service. Block Assembly and Blockchain run as single stateful instances, and the shipped example Cluster CRs pin every service to one replica except the Validator. See 2.6 Block Assembly Service for why.
This document provides an overview of each microservice, its responsibilities, and how it interacts with other components in the system.
2. Core Services¶
2.1 Asset Server¶
The Asset Server acts as an interface to various data stores, handling transactions, subtrees, blocks, and UTXOs. It uses the HTTP protocol for communication.
Key Responsibilities:
- Provide access to blockchain data
- Handle data retrieval requests from other services and external clients
- Serve as a facade for various data stores
Data Models:
- Blocks
- Block Headers
- Subtrees
- Extended Transactions
- UTXOs
Key Interactions:
- Interacts with UTXO Store, Blob Store (Subtree and TX Store), and Blockchain Server
- Provides data to other Teranode components and external clients over HTTP/WebSockets
HTTP Endpoints:
- getTransaction() and getTransactions()
- GetTransactionMeta()
- GetSubtree()
- GetBlockHeaders(), GetBlockHeader() and GetBestBlockHeader()
- GetBlock() and GetLastNBlocks()
- GetUTXO() and GetUTXOsByTXID()
You can read more about this service in the Asset Server documentation.
2.2 Propagation Service¶
The Propagation Service is responsible for receiving and forwarding transactions across the network.
Key Responsibilities:
- Receive transactions from the network through multiple communication channels (gRPC and HTTP)
- Perform initial sanity checks on transactions
- Forward valid transactions to the Validator Service
Key Interactions:
- Receives transactions from other nodes via gRPC or HTTP
- Forwards transactions to the Validator Service
Technology Stack:
- Go programming language
- HTTP for network communication
- gRPC and Protocol Buffers for service communication
You can read more about this service in the Propagation Service documentation.
2.3 Validator Service¶
The Validator Service checks transactions against network rules and updates their status in the UTXO store.
Key Responsibilities:
- Validate transactions against network rules and Bitcoin consensus rules
- Update transaction status in the UTXO store
- Forward validated transaction IDs to the Block Assembly Service
- Notify P2P subscribers about rejected transactions
Key Processes:
- Receiving transaction validation requests
- Validating transactions (including checks for double-spending)
- Updating UTXO store with new transaction data
- Propagating validated transactions to Block Assembly and Subtree Validation services
Data Model:
- Extended Transaction format
Technology Stack:
- Go programming language
- gRPC for service communication
- Kafka for message queuing (optional)
- BSV Blockchain libraries for transaction validation
You can read more about this service in the Validator Service documentation.
2.4 Subtree Validation Service¶
This service validates newly received subtrees, adds metadata, and persists them in the Subtree Store.
Key Responsibilities:
- Validate subtrees received from other nodes
- Add metadata to subtrees for block validation
- Store validated subtrees in the Subtree Store
Key Processes:
- Real-time validation of subtrees
- UTXO validation for transactions within subtrees
- Handling unvalidated transactions within subtrees
You can read more about this service in the Subtree Validation Service documentation.
2.5 Block Validation Service¶
The Block Validation Service processes new blocks, checking their validity before they are added to the blockchain.
Key Responsibilities:
- Validate new blocks
- Coordinate with Subtree Validation Service for missing subtrees
- Update the blockchain with validated blocks
Key Processes:
- Receiving blocks for validation
- Validating block structure, Merkle root, and block header
- Catching up after a parent block is not found
- Marking transactions as mined
Data Models:
- Blocks
- Subtrees
- Extended Transactions
- UTXOs
You can read more about this service in the Block Validation Service documentation.
2.6 Block Assembly Service¶
This service is responsible for creating subtrees and assembling block templates for miners.
Deployment model: Block Assembly is not horizontally scalable. It runs as a single stateful instance — one per Teranode node, i.e. one per cluster, not one per Kubernetes worker. There is no leader election or standby: every replica that starts is fully active and will serve mining traffic.
With more than one replica, a mining job exists only in the process that issued the candidate, so a solution routed to any other one is rejected with "job not found". Both replicas also write the same persisted BlockAssembler checkpoint, so they overwrite each other's view of the chain tip — a shared store does not fix this, it is part of the problem. How requests spread across replicas depends on how the Block Assembly service address is resolved at runtime, which makes the failure intermittent rather than immediate.
Block Assembly scales vertically (CPU and memory on its single instance) and via subtree sizing — see Dynamic Subtree Size Adjustment. The stateless services upstream (Propagation, Validator) scale horizontally as usual.
Key Responsibilities:
- Organize transactions into subtrees
- Create block templates from subtrees
- Broadcast new subtrees and blocks to the network
- Handle blockchain reorganizations and forks
Key Processes:
- Receiving transactions from the Validator Service
- Grouping transactions into subtrees
- Creating mining candidates
- Processing subtrees and blocks from other nodes
- Handling forks and conflicts
Data Models:
- Blocks
- Subtrees
- UTXOs
You can read more about this service in the Block Assembly Service documentation.
2.7 Blockchain Service¶
The Blockchain Service manages block updates and maintains the node's copy of the blockchain through a Finite State Machine (FSM) that coordinates blockchain state transitions.
Deployment model: like Block Assembly, the Blockchain Service is single-instance — one per Teranode node. Both shipped example Cluster CRs pin it to one replica.

Key Responsibilities:
- Add new blocks to the blockchain
- Manage block headers and subtree lists
- Provide blockchain state information to other services
- Handle block invalidation and chain reorganization

Key Processes:
- Adding new blocks to the blockchain
- Retrieving blocks and block headers
- Invalidating blocks
- Managing subscriptions for blockchain events
Data Model:
- Blocks (including block header, coinbase TX, and block merkle root)
You can read more about this service in the Blockchain Service documentation.
2.8 Alert Service¶
The Alert Service handles system-wide alerts and notifications, including UTXO freezing and block invalidation.
Key Responsibilities:
- Distribute important network alerts
- Manage alert prioritization and dissemination
- Handle UTXO freezing, unfreezing, and reassignment
- Manage peer banning and unbanning
- Handle block invalidation requests
Key Processes:
- UTXO freezing and unfreezing
- UTXO reassignment
- Block invalidation
- Peer management
You can read more about this service in the Alert Service documentation.
3. Overlay Services¶
3.1 Block Persister Service¶
This service post-processes blocks, adding transaction metadata and storing them as files.
Key Responsibilities:
- Decorate transactions in blocks with metadata
- Store processed blocks in a block data storage system
- Create and store UTXO addition and deletion files
Key Processes:
- Receiving and processing new block notifications
- Decorating transactions with UTXO metadata
- Creating and storing block, subtree, and UTXO files
Data Models:
- Blocks
- Subtrees
- UTXOs (additions and deletions)
You can read more about this service in the Block Persister Service documentation.
3.2 UTXO Persister Service¶
The UTXO Persister maintains an up-to-date record of all unspent transaction outputs.
Key Responsibilities:
- Process new blocks to update the UTXO set
- Maintain UTXO set files for each block
- Create and maintain an up-to-date UTXO file set for each block in the blockchain
Key Processes:
- Monitoring for new block files
- Processing UTXO additions and deletions
- Generating UTXO set files
- Tracking progress of processed blocks
Data Model:
- UTXO set (collection of unspent transaction outputs)
- UTXO components: TxID, Index, Value, Height, Script, Coinbase flag
Technology Stack:
- Go programming language
- Blob store for file storage
- BSV Blockchain libraries for blockchain operations
You can read more about this service in the UTXO Persister Service documentation.
3.3 P2P Service¶
The P2P Service manages peer-to-peer communications within the network.
Key Responsibilities:
- Handle peer discovery and connection management
- Facilitate message passing between nodes
- Manage subscriptions for blockchain events
- Handle WebSocket connections for real-time notifications

Key Processes:
- Peer discovery and connection
- Managing best block messages
- Handling blockchain messages (blocks, subtrees, mining)
- Processing TX validator messages
- Managing WebSocket notifications
You can read more about this service in the P2P Service documentation.
3.4 Legacy Service¶
The Legacy Service facilitates communication between Teranode and traditional BSV Blockchain nodes.
Key Responsibilities:
- Receive blocks and transactions from legacy nodes
- Disseminate new blocks to legacy nodes
- Transform data between BSV and Teranode formats
Key Processes:
- Receiving inventory notifications from BSV nodes
- Processing new blocks and converting them to Teranode format
- Handling requests from Teranode components for legacy data
You can read more about this service in the Legacy Service documentation.
3.5 RPC Service¶
The RPC Service provides compatibility with the Bitcoin RPC interface, allowing clients to interact with the Teranode node using standard Bitcoin RPC commands.
Key Responsibilities:
- Handle incoming RPC requests
- Process and validate RPC commands
- Interact with core Teranode services to fulfill requests
- Provide responses in Bitcoin-compatible format
Supported RPC Commands:
- clearbanned, createrawtransaction, generate, generatetoaddress, getbestblockhash, getblock, getblockbyheight, getblockchaininfo, getblockhash, getblockheader, getchaintips, getdifficulty, getinfo, getminingcandidate, getmininginfo, getpeerinfo, getrawmempool, getrawtransaction, help, invalidateblock, isbanned, listbanned, reconsiderblock, sendrawtransaction, setban, stop, submitminingsolution, version
Key Processes:
- Authenticating RPC requests
- Routing requests to appropriate handlers
- Executing commands and interacting with other Teranode services
- Formatting and returning responses
Technology Stack:
- Go programming language
- HTTP/HTTPS for RPC communication
- JSON for request/response formatting
You can read more about this service in the RPC Service documentation.
3.6 Pruner Service¶
The Pruner Service is an event-driven overlay service that removes stale UTXO data to prevent unbounded database growth.
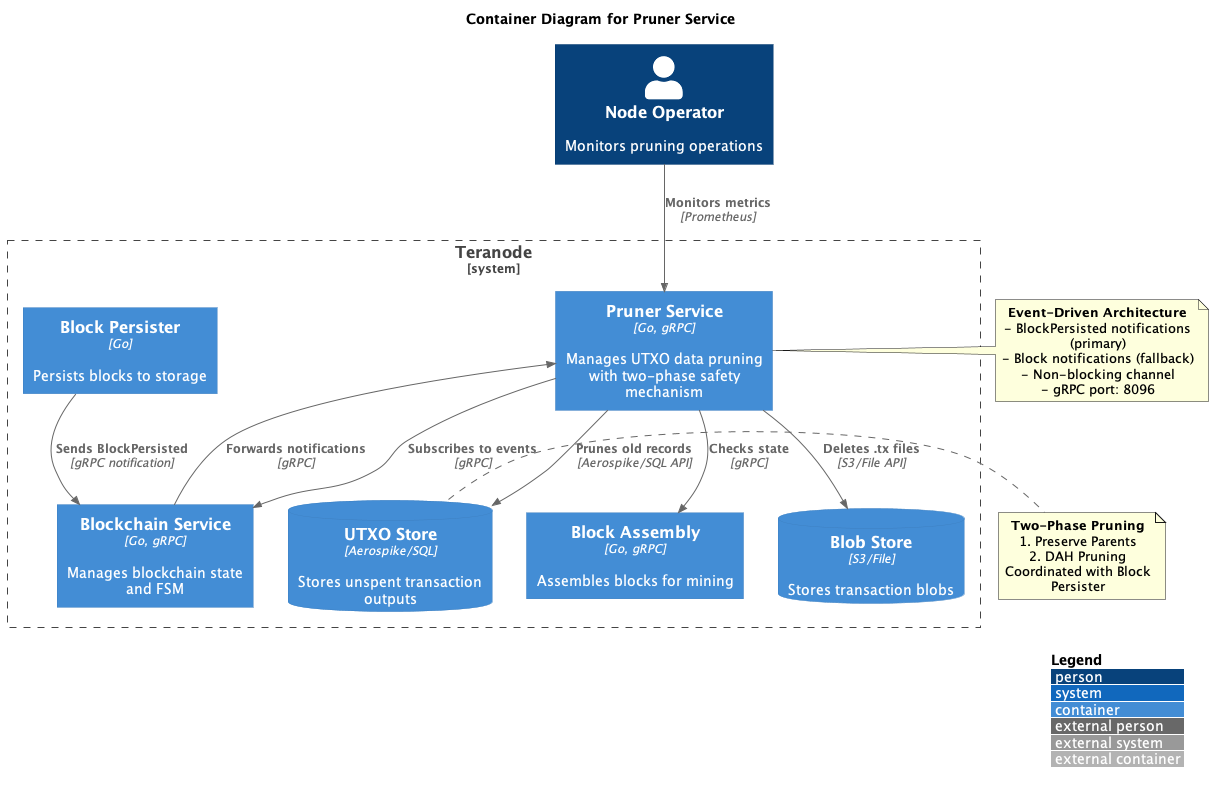
Key Responsibilities:
- Respond to
BlockPersistedorBlocknotifications — selected bypruner_block_trigger— instead of polling - Preserve parent transactions of old unmined transactions so they remain available for resubmission
- Remove UTXO records marked for deletion once they reach their delete-at-height
- Coordinate with the Block Persister so transaction data stays accessible until
.subtree_datafiles are created - Clean up external transaction blobs from blob storage (S3/filesystem)
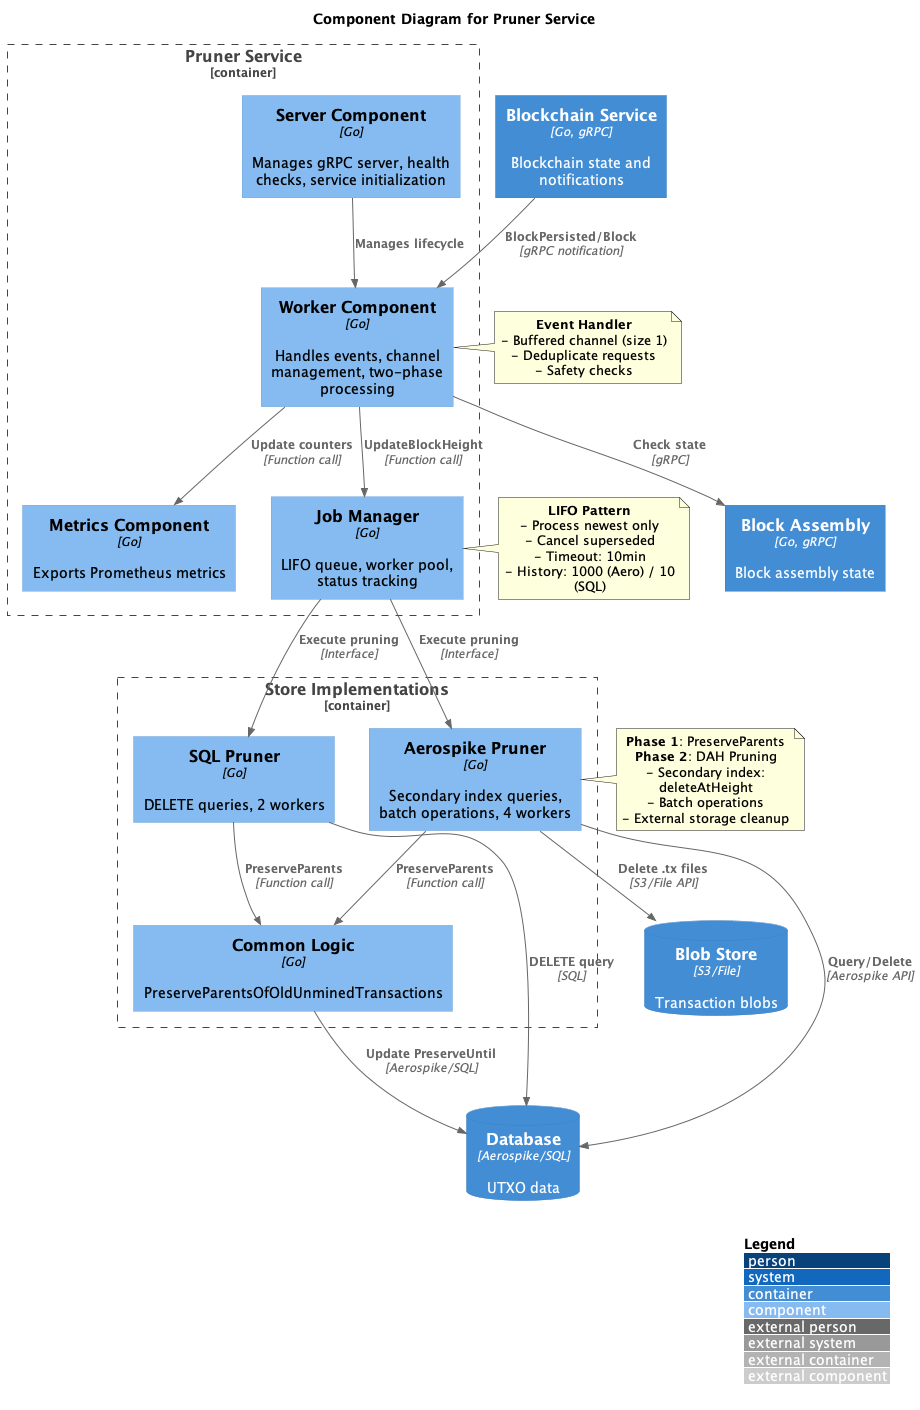
Key Processes:
- Subscribing to blockchain notifications to trigger pruning runs
- Running a two-phase pruning process to prevent data loss
- Coordinating with Block Persister during catchup
- Managing a job queue and worker pool for pruning and blob-deletion work
You can read more about this service in the Pruner Service documentation.
4. Stores¶
4.1 TX and Subtree Store (Blob Server)¶
The Blob Server is a generic datastore used for storing transactions (extended tx) and subtrees.
Key Responsibilities:
- Store and retrieve transaction data
- Store and retrieve subtree data
- Provide a common interface for various storage backends
Supported Storage Backends:
- File System (
file://) - Amazon S3 and S3-compatible services such as MinIO and SeaweedFS (
s3://) - HTTP (
http://) - In-memory storage (
memory://) - Null/no-op (
null://)
Key Interactions:
- Used by Asset Server for retrieving transaction and subtree data
- Utilized by Block Assembly for storing and retrieving subtrees
- Accessed by Block Validation for transaction and subtree verification
Data Models:
- Extended Transaction Data Model
- Subtree Data Model
You can read more about this store in the Blob Store documentation.
4.2 UTXO Store¶
The UTXO Store is responsible for tracking spendable UTXOs based on the longest honest chain-tip in the network.
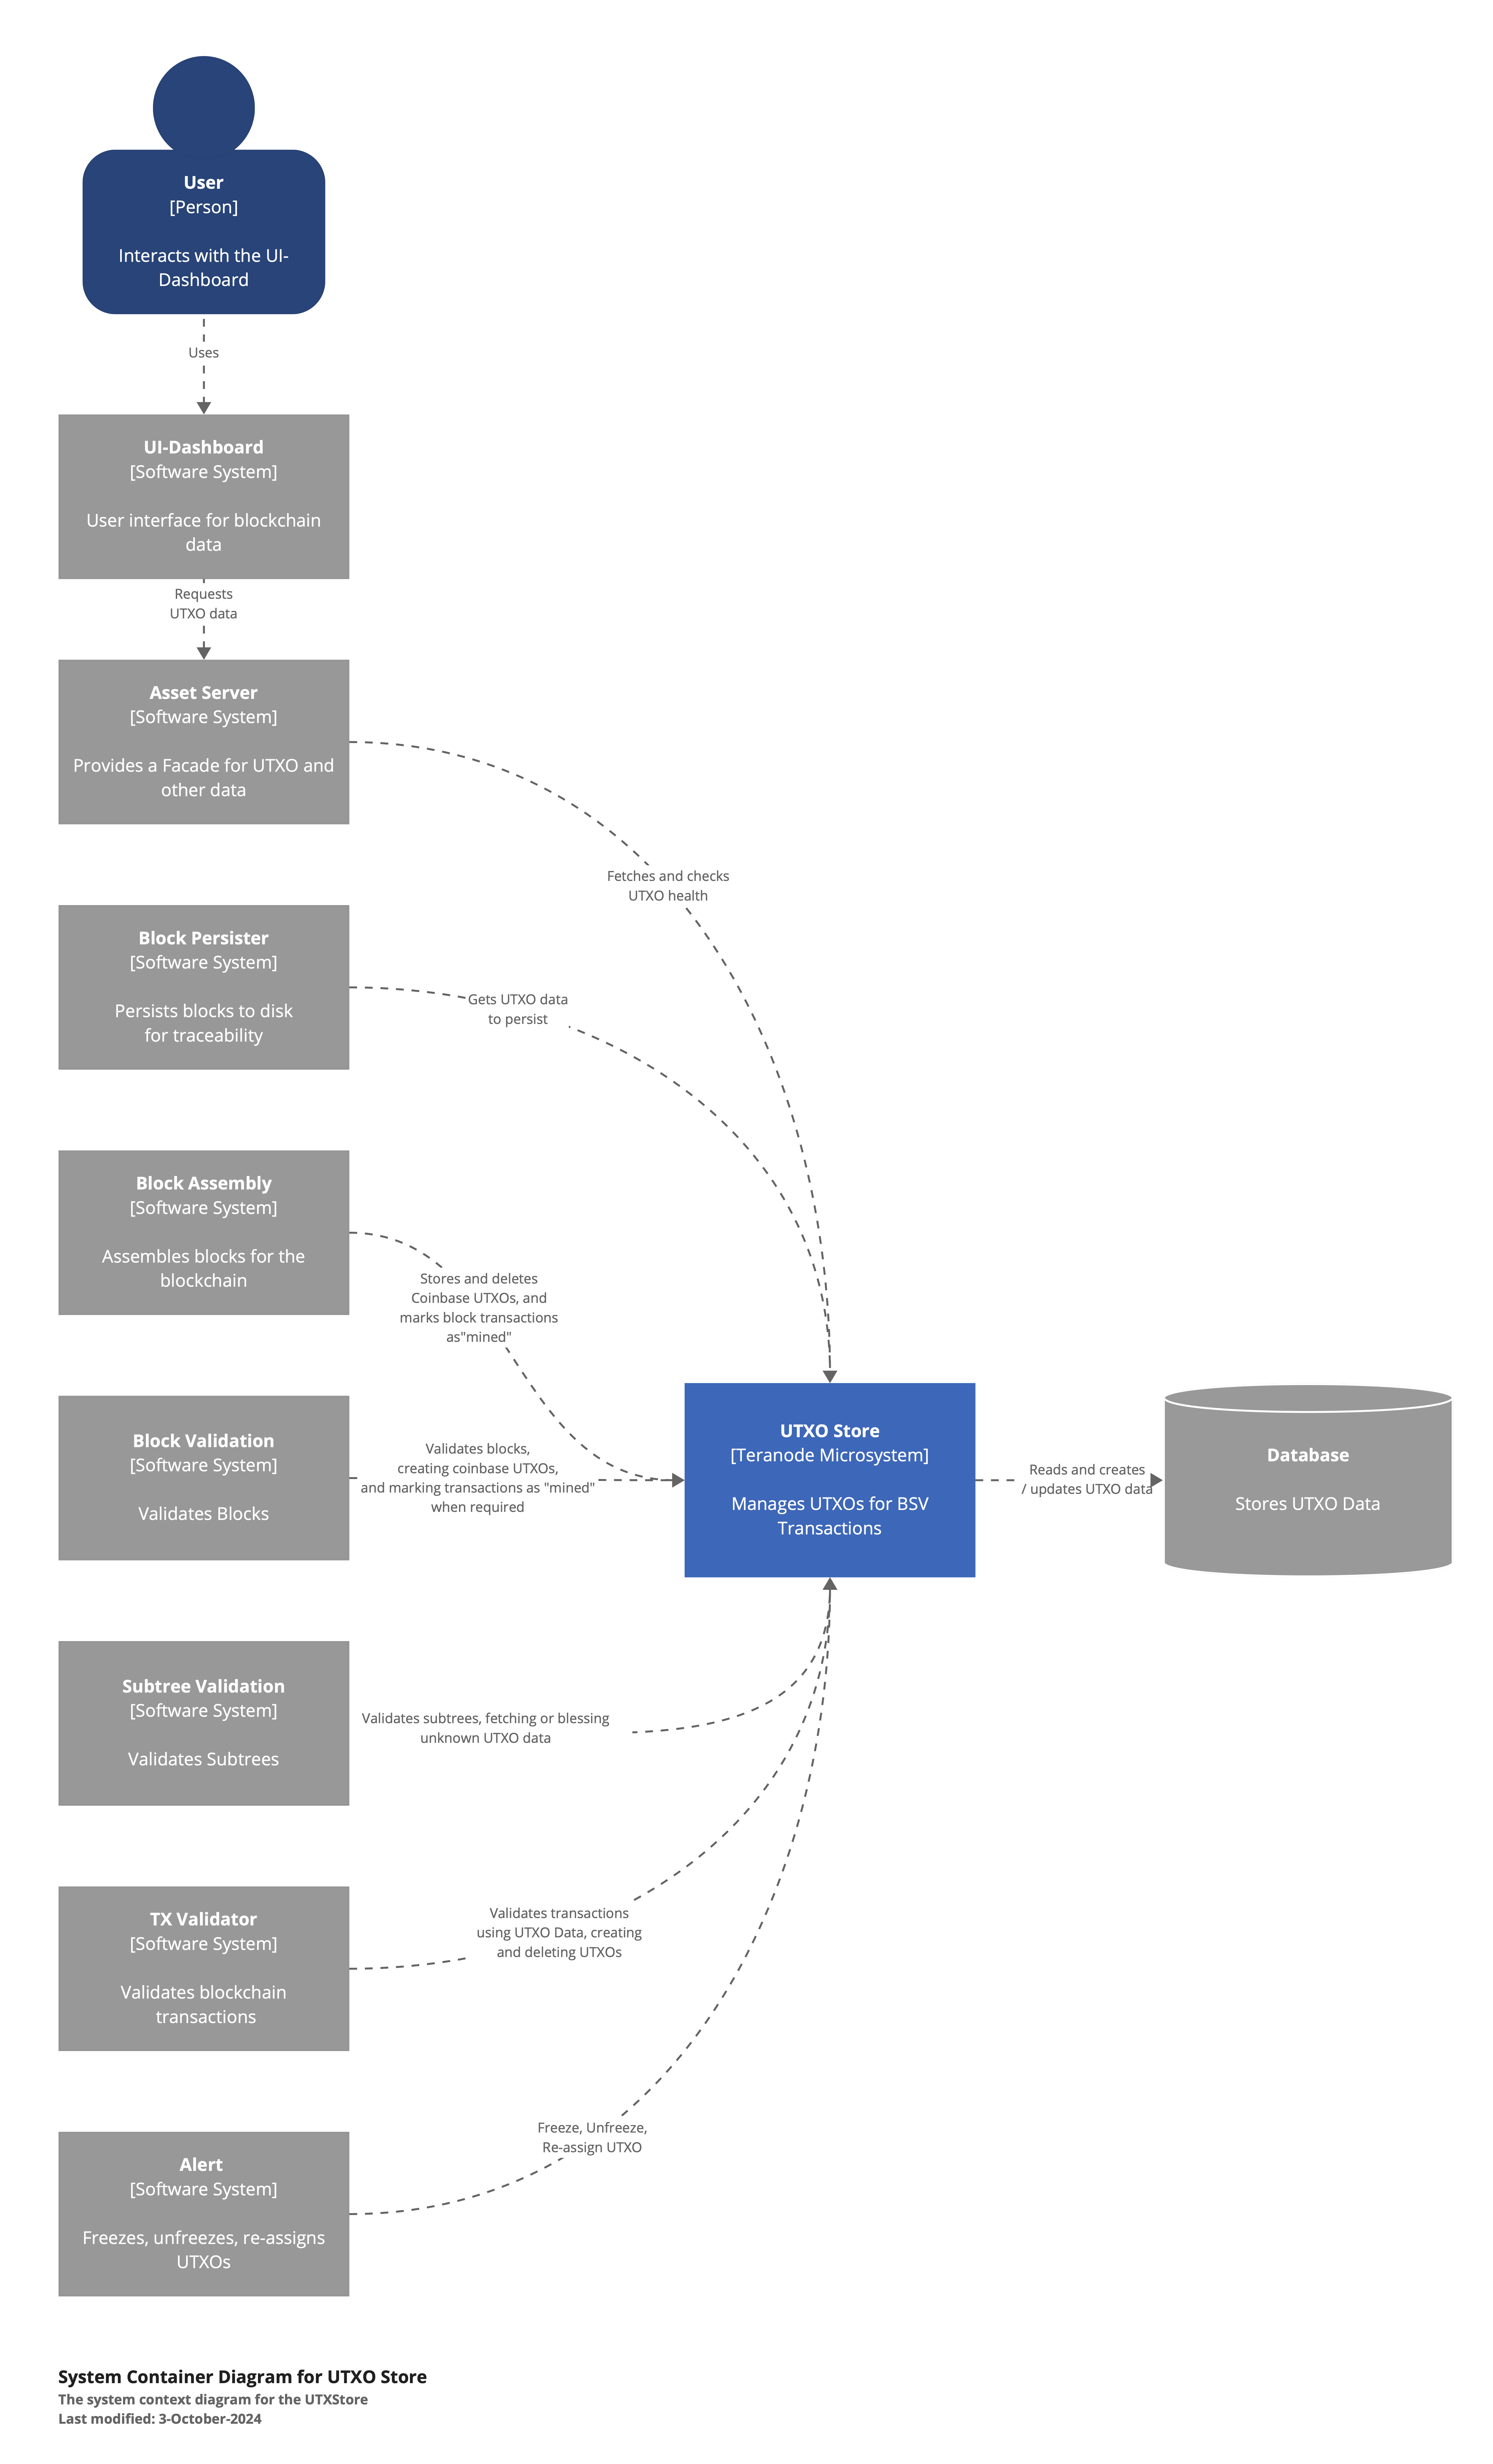
Key Responsibilities:
- Maintain the current UTXO set
- Handle UTXO creation, spending, and deletion
- Manage block height for determining UTXO spendability
- Support freezing, unfreezing, and reassigning UTXOs
Supported Storage Backends:
- Aerospike (primary production datastore)
- In-memory store
- SQL (PostgreSQL and SQLite)
- Nullstore (for testing)
Key Interactions:
- Used by Asset Server for UTXO data retrieval
- Accessed by Block Persister for UTXO metadata
- Utilized by Block Assembly for coinbase UTXO management
- Interacts with Block Validation for UTXO verification
- Supports Transaction Validator for UTXO operations
Data Model:
- UTXO Meta Data, including transaction details, parent transaction hashes, block IDs, fees, and other metadata
You can read more about this store in the UTXO Store documentation.
5. Other Components¶
5.1 Kafka Message Broker¶
Kafka serves as the messaging middleware for inter-service communication in Teranode.
Key Responsibilities:
- Facilitate asynchronous communication between services
- Ensure reliable message delivery
- Support high-throughput data streaming
Key Topics and Use Cases:
kafka_validatortxsConfig: Optional transport for new transaction notifications from Propagation to Validator. Empty by default insettings.confand populated only in the.operatorcontext; when empty, no producer and no consumer group are created and Propagation invokes the Validator directly. See §6.1kafka_txmetaConfig: Used for sending new UTXO metadata from Validator to Subtree Validationkafka_rejectedTxConfig: Used for notifying P2P about rejected transactionskafka_blocksConfig: Used for propagating new blocks from P2P to Block Validationkafka_subtreesConfig: Used for sending new subtrees from P2P to Subtree Validationkafka_blocksFinalConfig: Used for sending finalized blocks from Blockchain to the Legacy P2P service (netsync.SyncManager). The Block Persister does not consume this topic — it polls the Blockchain service over gRPC (GetBlocksNotPersisted) insteadkafka_invalidBlocksConfig: Used for notifying P2P about blocks that failed validation, for peer reputation managementkafka_invalidSubtreesConfig: Used for notifying P2P about subtrees that failed validation, for peer quality trackingkafka_txPolicyRejectedConfig: Used for sending consensus-valid but policy-rejected transactions from Validator to Subtree Validationkafka_legacyInvConfig: Used by the Legacy Sync Manager to bridge legacy Bitcoin wire protocol inventory messages to and from Kafka
Key Features:
- Supports high-throughput data streaming
- Provides fault-tolerance and durability
- Allows for scalable message consumption
You can read more about how Kafka is used in the Kafka usage documentation.
5.2 Miners¶
Miners are responsible for the computational work of finding valid blocks.
Key Responsibilities:
- Perform proof-of-work calculations
- Broadcast newly found blocks
6. Interaction Patterns¶
The Teranode microservices communicate through a combination of synchronous gRPC calls and asynchronous Kafka message streams, creating an event-driven architecture that enables high throughput and loose coupling between components.
Transaction Processing Flow:
- Propagation Service receives incoming transactions from the network through multiple channels (gRPC, HTTP, UDP multicast) and hands each transaction to the Validator. That handoff runs over the
kafka_validatortxsConfigtopic only when the topic is configured; it is empty in the committed defaults, and withuseLocalValidator = true(also the committed default) Propagation calls an in-process Validator directly - Validator Service validates transactions against Bitcoin consensus rules and network policies, updates the UTXO Store with transaction metadata, and publishes the resulting UTXO metadata to Kafka (
kafka_txmetaConfig) for Subtree Validation - Block Assembly Service does not consume from Kafka: the Validator calls it directly over gRPC (
AddTx/AddTxBatch, viablockAssembler.Store()), because the transaction must land in the current mining candidate before the caller proceeds. Block Assembly organizes the transactions it receives into subtrees for efficient block construction and mining - Subtree Validation Service validates newly received subtrees and coordinates with the Validator Service for any missing transaction data
Block Processing Flow:
- P2P Service receives new blocks and subtrees from peer nodes and propagates them via Kafka to the Block Validation and Subtree Validation services
- Block Validation Service coordinates with the Subtree Validation Service to verify all subtrees within a block, ensuring data integrity before acceptance
- Blockchain Service maintains the blockchain state machine, managing block additions, chain reorganizations, and finality determinations
- When a block is finalized, Blockchain Service publishes it via Kafka (
blocks-final) to the Legacy P2P service, which uses it to announce new blocks to legacy (pre-libp2p) peers. The Block Persister does not consume this topic; it polls the Blockchain service over gRPC (GetBlocksNotPersisted) for blocks awaiting long-term storage
Data Access Patterns:
- Asset Server provides a unified HTTP/WebSocket interface for querying blockchain data, acting as a facade over the UTXO Store, Blob Store, and Blockchain Store
- UTXO Store serves as a central state management component, interacting with multiple services (Validator, Block Assembly, Block Validation) for UTXO operations and double-spend prevention
- Blob Store provides persistent storage for transactions and subtrees, accessed by Asset Server, Block Assembly, and Block Validation services
6.1 Choosing gRPC vs. Kafka for a New Communication Path¶
When adding a new communication path between services, pick the transport based on what the path actually needs, not on convenience or precedent alone. There are three options in Teranode, not two — gRPC request/response, the Blockchain notification stream, and Kafka:
- Use gRPC when the call is synchronous request/response and the caller cannot make
progress until it gets a result (success/failure, or a value it needs right now).
Examples already in the codebase:
- Validator → Block Assembly
Store(): the Validator calls Block Assembly directly over gRPC (not Kafka) because the transaction must land in the current mining candidate without delay, and the caller needs to know the call succeeded. - Block Validation / Block Assembly → Blockchain
AddBlock: the caller needs to know whether the block was accepted before proceeding (e.g. to mark it mined). - Block Validation → Subtree Validation
CheckBlockSubtrees: validation cannot continue until it learns whether the referenced subtrees are known/valid.
- Validator → Block Assembly
- Use the Blockchain notification subscription when the event is a chain-state change
that several services need to hear about — block added, block invalidated, reorg, FSM
transition. This is a gRPC server-streaming RPC,
rpc Subscribe (SubscribeRequest) returns (stream Notification)(services/blockchain/blockchain_api/blockchain_api.proto), andSendNotificationon the Blockchain server broadcasts to all active subscribers without blocking on any of them. Seven services subscribe today: P2P, Block Assembly, Block Validation, Subtree Validation, Asset (main-chain cache), UTXO Persister and Pruner. Prefer this over introducing a new Kafka topic for chain-state fan-out — there is no broker or topic configuration to add, and every service that needs it already holds a blockchain client. - Use Kafka when the path is asynchronous, fire-and-forget, one-to-many, or the
producer does not need to know whether or when a consumer processes the message.
Examples already in the codebase:
- Validator → Subtree Validation (
kafka_txmetaConfig) and Validator → P2P (kafka_rejectedTxConfig): notifications that the Validator emits without caring who consumes them or when. - P2P → Block Validation / Subtree Validation (
kafka_blocksConfig,kafka_subtreesConfig): network events fanned out for eventual processing, decoupling ingestion rate from validation rate. - Blockchain → Legacy P2P (
kafka_blocksFinalConfig): a finalized block is announced to legacy (pre-libp2p) peers bynetsync.SyncManager; the producer does not wait for, or learn about, delivery. Note this is the topic's only real consumer — the Block Persister does not consume it, it polls the Blockchain service over gRPC (GetBlocksNotPersisted), waking everyblockpersister_persistSleep(default 10s), because it needs to drive its own pace and record progress back to the Blockchain service. Long-running "queue it for eventual heavy work" paths in Teranode are pull loops, not topics. - Propagation → Validator (
kafka_validatortxsConfig) — opt-in, off in the committed defaults: when the topic is configured, Propagation hands off a new transaction and moves on without waiting for validation.kafka_validatortxsConfigis empty insettings.confand populated only in the.operatorcontext; when it is empty no producer and no consumer group are created. On top of that,useLocalValidator = trueis the committed default, sodaemon/daemon_stores.gohands Propagation an in-process*Validatorrather than a gRPC stub — the default path is a function call, not a network hop. This is the one path in the codebase where the transport is a deployment decision rather than a design decision.
- Validator → Subtree Validation (
Rule of thumb: if the calling code needs the result before it can proceed (or needs
to know the call failed), use gRPC. If the event is a chain-state change that several
services react to, use the Blockchain Subscribe stream. If the producer only needs to
announce that something happened, and doesn't care who's listening or when they get to it,
use Kafka. Before committing to Kafka, check these four things:
- Fan-out is per consumer group, not per consumer. Within one group, each partition is
assigned to a single instance, so exactly one instance sees each message — that is how
a consumer scales horizontally. To have several independent consumers each see every
message, each needs its own group ID:
daemon/daemon_services.gobuilds per-service group IDs, whiledaemon/daemon_kafka.godeliberately appends a random per-process suffix to thetxmetagroup so every Subtree Validation pod consumes the full stream. Getting this backwards produces either duplicated work or a silent single-instance bottleneck. - Durability is bounded by the topic's retention, not by "Kafka is persistent".
kafka_blocksConfig,kafka_blocksFinalConfig,kafka_txmetaConfigand the.operatorkafka_validatortxsConfigare allretention=60000(60 s) insettings.conf; onlykafka_subtreesConfig(30 min) andkafka_rejectedTxConfig(10 min) give a meaningful window. A consumer down for longer than the retention drops messages rather than catching up. If a new path must tolerate longer outages, raise retention deliberately or design an explicit catch-up path (as the Block Persister does withGetBlocksNotPersisted). - Payload size has a ceiling.
validator_kafka_maxMessageBytesis ~1 MB (1048576 code default, 1048500 insettings.conf), matching the Kafka broker default, and Propagation already needs an HTTP fallback for transactions above it —validateTransactionViaHTTP, which hard-fails when no validator HTTP endpoint is configured. The Blockchain service also warns when ablocks-finalmessage crosses 500 KB. If a new path can carry payloads near that limit, either keep the message a reference (hash + metadata, payload in a store) or plan the fallback leg up front. - Kafka orders messages only within a partition. A path that needs global ordering is
therefore limited to one partition, which caps how far a consumer group can be scaled out
— partitions are the unit of parallelism within a group. Ordering is not recoverable by
tuning after the fact: it forces either a single partition or a redesign.
settings.confcarries the comment "tx validation order is critical so we cannot have mutiple partitions" [sic] abovekafka_validatortxsConfig, though the.operatorURL that follows it is configured withpartitions=${KAFKA_PARTITIONS_HIGH}(8) — treat ordering as something to establish for your own path rather than something inherited.
7. Related Resources¶
- Teranode Architecture Overview
-
Core Services: